

Overview
e6data’s Hybrid Data Lakehouse enables enterprises to query data across clouds, regions, and on-premises without migrating data. Powered by a federated SQL engine and hybrid cluster architecture, this feature ensures data autonomy, regulatory compliance, and cost efficiency, all while presenting a unified query interface to the user.This feature is currently in active development and only available to users on request.
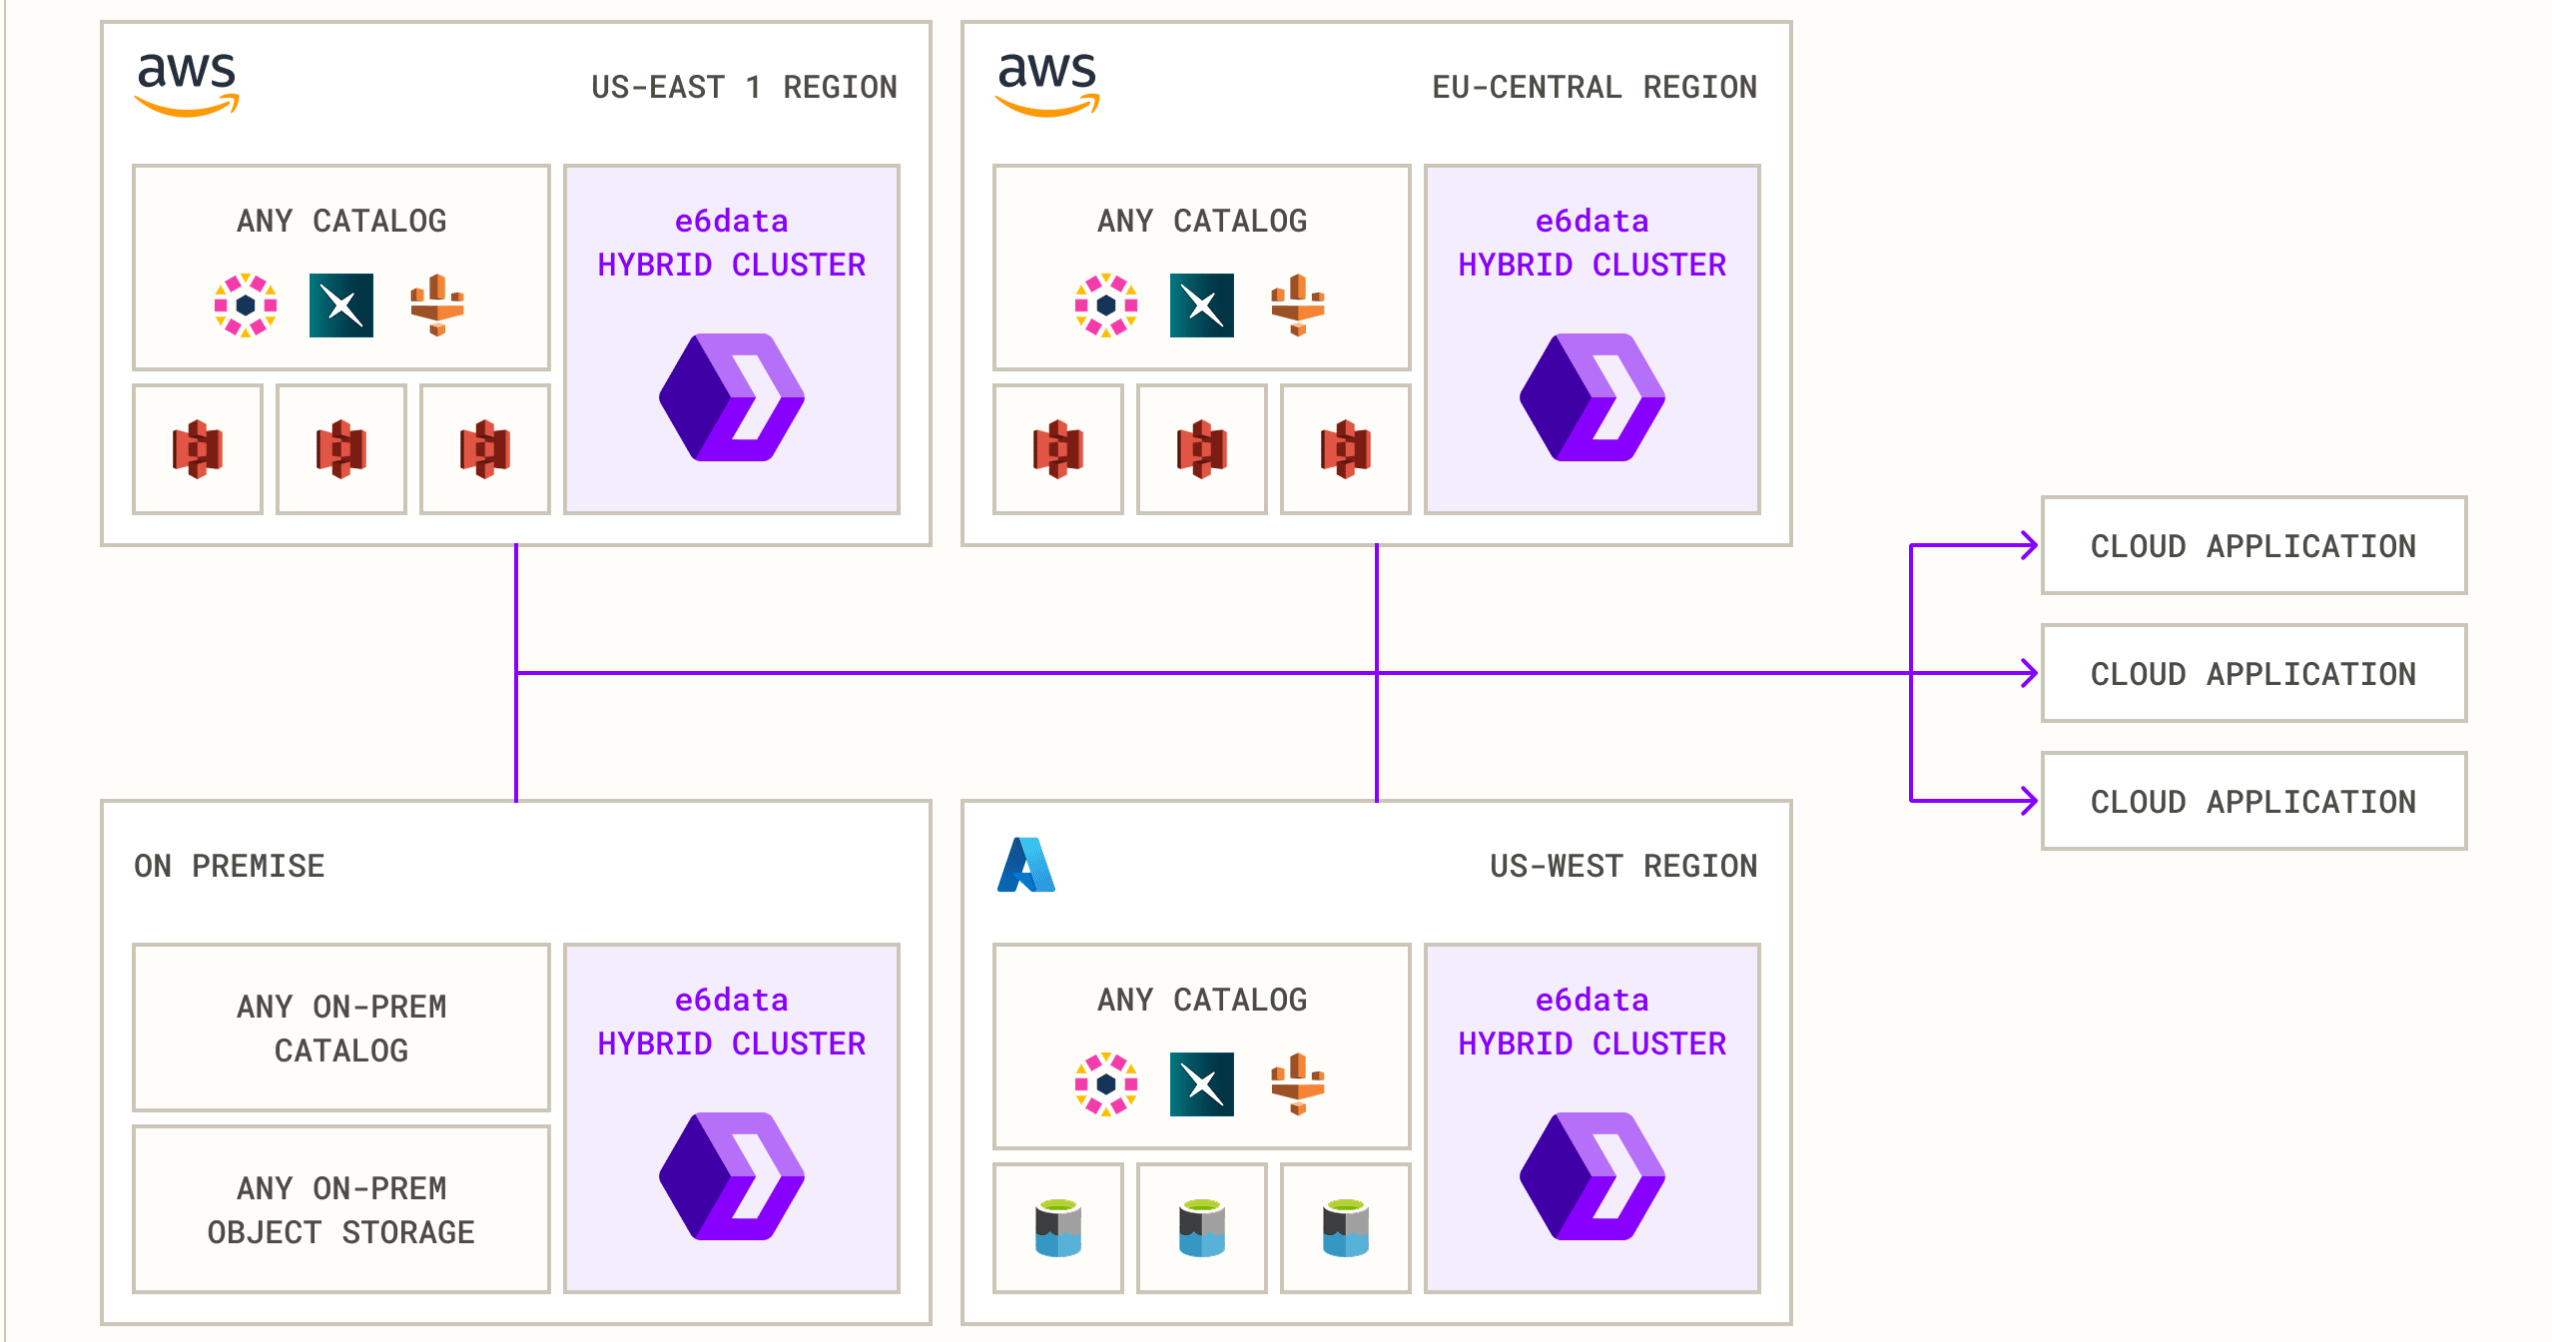
What It Does
- Connects heterogeneous data sources across clouds, regions, or ownership boundaries.
- Provides a federated SQL interface for seamless querying.
- Minimizes data movement by pushing compute to where the data lives.
- Enhances governance, security, and cost efficiency in distributed environments.
How It Works
The hybrid lakehouse is built using a hybrid cluster architecture:
Even though data and compute are different layers and actions, the user always experiences a single, unified query layer.
How to Set It Up
- Identify data sources and federation rules.
- Perform capacity planning for each region or cloud.
- Choose metastore model:
- Centralized (common metastore)
- Federated (per region/cloud)
- Use e6data’s automated deployment scripts to:
- Provision hybrid clusters
- Configure auto-scaling
- Wire all clients to the main cluster
Supported Platforms & Features
- Multi-cloud (AWS, Azure, GCP)
- Object storage (S3, ADLS, GCS)
- Metastores (Hive, AWS Glue, etc.)
- Full compatibility with e6data SQL workloads
Future Enhancements
- Access control policies must be defined centrally at the main cluster.
- Latency may be higher if most data resides away from the main cluster.
- Currently supports statically defined main clusters (dynamic routing is in progress).
Use Cases
- Global enterprises with compliance requirements in multiple geographies
- Organizations seeking to reduce cross-region/cloud egress fees
- Businesses wanting to avoid vendor lock-in and promote cloud neutrality
- Teams managing data silos across departments or subsidiaries